


이번 장에서는 지금까지 배운 내용을 한 번에 묶어 작은 데이터 처리 도구를 만들어 본다. C++을 떠올리면 많은 사람이 게임 엔진, 그래픽스, 운영체제, 임베디드 같은 분야를 먼저 생각한다. 물론 모두 맞다. 하지만 C++은 대량의 텍스트 파일을 빠르게 읽고, 필요한 값만 뽑아 집계하고, 결과 파일을 만들어 내는 데이터 처리 도구를 만들 때도 매우 강력하다.
이번에 만들 프로그램은 CSV 파일을 읽어 상품 판매 데이터를 집계한다. CSV는 쉼표로 열을 구분하는 단순한 텍스트 파일 형식이다. 엑셀, 구글 스프레드시트, 데이터베이스 내보내기, 로그 분석 도구에서 흔히 볼 수 있다.
예를 들어 다음과 같은 파일이 있다고 하자.
date,region,product,quantity,unit_price
2026-05-01,Seoul,Keyboard,2,79000
2026-05-01,Busan,Mouse,5,25000
2026-05-02,Seoul,Monitor,1,230000
2026-05-02,Seoul,Mouse,3,25000
2026-05-03,Incheon,Keyboard,1,79000
우리가 만들 도구는 이 파일을 읽고 지역과 상품별로 판매 건수, 판매 수량, 매출 합계, 평균 매출을 계산한 뒤 다시 CSV 파일로 저장한다. 프로그램은 작지만, 실제 데이터 처리 프로그램의 뼈대가 거의 그대로 들어 있다. 파일을 읽고, 문자열을 나누고, 구조체로 저장하고, 컨테이너로 관리하고, 알고리즘으로 정리하고, 결과를 파일로 내보낸다.
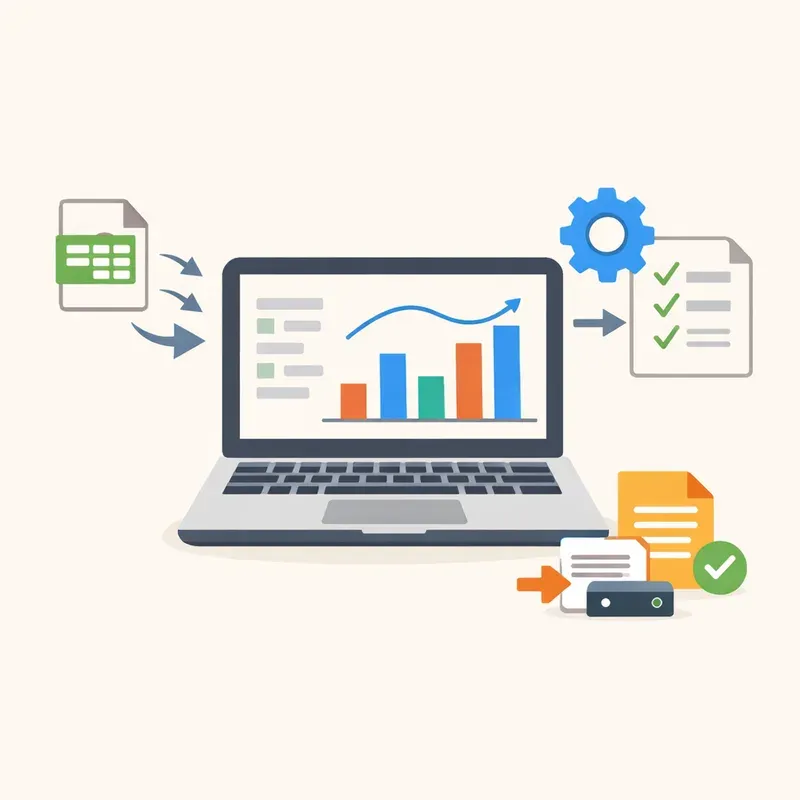
데이터 처리 프로그램의 기본 흐름
데이터 처리 프로그램은 보통 화려한 화면보다 흐름이 중요하다. 입력이 있고, 변환이 있고, 출력이 있다. 이 세 단계가 흔들리지 않으면 프로그램은 작게 시작해도 충분히 크게 확장할 수 있다.
이번 장의 프로그램은 다음 흐름으로 움직인다.
CSV 파일을 연다.
첫 줄에서 헤더를 읽어 열 이름과 위치를 파악한다.
나머지 줄을 하나씩 읽어 필드로 분리한다.
각 행을
SaleRecord구조체로 변환한다.std::vector에 전체 레코드를 저장한다.std::map또는std::unordered_map으로 그룹별 집계를 만든다.집계 결과를
std::vector로 옮긴 뒤 정렬한다.결과를 새로운 CSV 파일로 저장한다.
이 흐름은 판매 데이터뿐 아니라 접속 로그, 센서 데이터, 주문 내역, 주식 거래 기록, 게임 플레이 로그를 다룰 때도 비슷하게 적용된다. 데이터의 모양은 바뀌어도 구조는 크게 달라지지 않는다.
예제 프로젝트의 입력과 출력
먼저 입력 파일의 형식을 정하자. 파일 이름은 sales.csv라고 하겠다.
date,region,product,quantity,unit_price
2026-05-01,Seoul,Keyboard,2,79000
2026-05-01,Busan,Mouse,5,25000
2026-05-02,Seoul,Monitor,1,230000
2026-05-02,Seoul,Mouse,3,25000
2026-05-03,Incheon,Keyboard,1,79000
2026-05-03,Busan,Monitor,2,230000
각 열의 의미는 단순하다. date는 판매 날짜, region은 지역, product는 상품명, quantity는 판매 수량, unit_price는 단가다. 매출은 quantity * unit_price로 계산할 수 있다.
프로그램은 다음과 같은 결과 파일을 만든다.
region,product,count,quantity,revenue,average_revenue
Busan,Monitor,1,2,460000.00,460000.00
Seoul,Monitor,1,1,230000.00,230000.00
Busan,Mouse,1,5,125000.00,125000.00
Seoul,Keyboard,1,2,158000.00,158000.00
Incheon,Keyboard,1,1,79000.00,79000.00
Seoul,Mouse,1,3,75000.00,75000.00
출력은 매출 합계가 큰 순서로 정렬한다. 이처럼 입력 파일보다 출력 파일이 더 작고 의미 있는 형태가 되는 것이 집계 프로그램의 핵심이다. 원본 데이터는 길고 지저분할 수 있지만, 결과는 의사결정에 바로 쓸 수 있어야 한다.
레코드 구조체 설계하기
CSV의 한 행은 프로그램 안에서 하나의 객체로 표현할 수 있다. 여기서는 클래스를 복잡하게 만들 필요가 없으므로 단순한 구조체를 사용하자.
struct SaleRecord {
    std::string date;
    std::string region;
    std::string product;
    int quantity = 0;
    double unitPrice = 0.0;

    double revenue() const {
        return quantity * unitPrice;
    }
};SaleRecord는 입력 데이터 한 줄을 나타낸다. date, region, product는 문자열이고, quantity는 정수, unitPrice는 실수다. revenue() 함수는 한 행의 매출을 계산한다.
여기서 중요한 점은 문자열 상태 그대로 모든 것을 처리하지 않는다는 것이다. CSV 파일에서 읽은 값은 처음에는 모두 문자열이다. 하지만 수량과 단가는 숫자로 다루어야 한다. 숫자를 문자열 상태로 계속 들고 있으면 매번 계산할 때 변환이 필요하고, 실수할 가능성도 커진다.
좋은 데이터 처리 프로그램은 입력 단계에서 데이터를 의미 있는 타입으로 바꾼다. 수량은 int, 단가는 double, 날짜는 지금은 단순 문자열로 두지만 필요하다면 나중에 날짜 타입으로 바꿀 수 있다. 타입을 제대로 정하면 이후 코드는 훨씬 단단해진다.
집계 결과를 담을 구조체도 필요하다.
struct Summary {
    int count = 0;
    int quantity = 0;
    double revenue = 0.0;

    void add(const SaleRecord& record) {
        ++count;
        quantity += record.quantity;
        revenue += record.revenue();
    }

    double averageRevenue() const {
        if (count == 0) {
            return 0.0;
        }
        return revenue / count;
    }
};Summary는 여러 판매 레코드를 하나로 모은 결과다. count는 판매 기록 개수, quantity는 총 판매 수량, revenue는 총매출이다. add() 함수는 레코드 하나를 집계에 반영한다.
이런 식으로 작은 구조체에 의미 있는 동작을 넣어 두면 코드가 읽기 쉬워진다. 집계하는 쪽에서는 summary.add(record)라고 쓰면 된다. count를 증가시키고, 수량을 더하고, 매출을 계산하는 세부 과정은 Summary 내부로 들어간다.
CSV 한 줄을 필드로 나누기
CSV는 단순해 보이지만 생각보다 조심할 점이 많다. 가장 쉬운 방법은 쉼표를 기준으로 문자열을 나누는 것이다. 하지만 상품명에 쉼표가 들어갈 수도 있다.
date,region,product,quantity,unit_price
2026-05-01,Seoul,"Keyboard, Wireless",2,79000
이 경우 Keyboard, Wireless는 하나의 필드다. 단순히 모든 쉼표에서 자르면 잘못된 결과가 나온다. 그래서 최소한 큰따옴표 안의 쉼표는 구분자로 보지 않는 처리가 필요하다.
먼저 공백을 정리하는 trim() 함수를 만들자.
#include <cctype>
#include <string>

std::string trim(const std::string& text) {
    std::size_t begin = 0;

    while (begin < text.size() &&
           std::isspace(static_cast<unsigned char>(text[begin]))) {
        ++begin;
    }

    std::size_t end = text.size();

    while (end > begin &&
           std::isspace(static_cast<unsigned char>(text[end - 1]))) {
        --end;
    }

    return text.substr(begin, end - begin);
}std::isspace는 문자 하나가 공백인지 확인한다. 여기서 static_cast<unsigned char>를 사용하는 이유는 char가 음수로 해석될 수 있는 환경에서 안전하게 처리하기 위해서다. 이런 작은 습관이 플랫폼 차이로 생기는 이상한 버그를 줄여 준다.
이제 CSV 한 줄을 필드 목록으로 나누는 함수를 작성하자.
#include <vector>

std::vector<std::string> splitCsvLine(const std::string& line) {
    std::vector<std::string> fields;
    std::string field;
    bool inQuotes = false;

    for (std::size_t i = 0; i < line.size(); ++i) {
        char ch = line[i];

        if (ch == '"') {
            if (inQuotes && i + 1 < line.size() && line[i + 1] == '"') {
                field.push_back('"');
                ++i;
            } else {
                inQuotes = !inQuotes;
            }
        } else if (ch == ',' && !inQuotes) {
            fields.push_back(trim(field));
            field.clear();
        } else {
            field.push_back(ch);
        }
    }

    fields.push_back(trim(field));
    return fields;
}
이 함수는 큰따옴표 안에 있는지 inQuotes로 기억한다. 쉼표를 만나도 큰따옴표 안이라면 필드 구분자로 처리하지 않는다. 또한 CSV에서는 큰따옴표 자체를 표현할 때 ""처럼 두 번 쓰는 경우가 있는데, 이 코드도 그 정도는 처리한다.
물론 이 함수가 세상의 모든 CSV를 완벽하게 처리하는 것은 아니다. 줄바꿈이 필드 안에 들어가는 CSV, 다양한 문자 인코딩 문제, 매우 복잡한 오류 복구까지 다루려면 더 정교한 파서가 필요하다. 하지만 학습용 도구나 사내에서 형식이 통제된 CSV 파일을 처리하기에는 충분한 출발점이다.
헤더를 읽고 열 위치 찾기
CSV 파일의 첫 줄은 보통 헤더다.
date,region,product,quantity,unit_price헤더를 사용하는 이유는 열 순서가 바뀌어도 프로그램이 대응할 수 있게 하기 위해서다. 만약 무조건 첫 번째 열은 날짜, 두 번째 열은 지역이라고 가정하면 파일 형식이 조금만 바뀌어도 프로그램이 틀어진다.
헤더 이름과 열 번호를 연결하기 위해 std::unordered_map을 사용할 수 있다.
#include <string>
#include <unordered_map>
#include <vector>

std::unordered_map<std::string, std::size_t>
makeHeaderIndex(const std::vector<std::string>& headers) {
    std::unordered_map<std::string, std::size_t> index;

    for (std::size_t i = 0; i < headers.size(); ++i) {
        index[headers[i]] = i;
    }

    return index;
}
예를 들어 index["region"]은 region 열이 몇 번째인지 알려 준다. 여기서는 헤더 이름으로 바로 찾는 작업이 많기 때문에 평균적으로 빠른 검색을 제공하는 std::unordered_map이 잘 어울린다.
필수 헤더가 있는지도 확인해야 한다.
#include <stdexcept>

void validateHeaders(const std::unordered_map<std::string, std::size_t>& index) {
    const char* required[] = {
        "date",
        "region",
        "product",
        "quantity",
        "unit_price"
    };

    for (const char* name : required) {
        if (index.find(name) == index.end()) {
            throw std::runtime_error(std::string("missing header: ") + name);
        }
    }
}
여기서는 필수 헤더가 없으면 예외를 던진다. 입력 파일 형식이 잘못되었으므로 더 진행해 봐야 올바른 결과를 만들 수 없다. 이런 실패는 조용히 무시하면 안 된다. 빨리 발견하고 명확한 메시지를 보여 주는 편이 낫다.
문자열을 숫자로 바꾸기
CSV에서 읽은 값은 모두 문자열이다. quantity와 unit_price는 숫자로 바꿔야 한다. 이번 예제에서는 std::from_chars를 사용한다.
#include <charconv>
#include <optional>
#include <string>
#include <system_error>

std::optional<int> parseInt(const std::string& text) {
    int value = 0;
    const char* first = text.data();
    const char* last = text.data() + text.size();

    auto result = std::from_chars(first, last, value);

    if (result.ec != std::errc{} || result.ptr != last) {
        return std::nullopt;
    }

    return value;
}

std::optional<double> parseDouble(const std::string& text) {
    double value = 0.0;
    const char* first = text.data();
    const char* last = text.data() + text.size();

    auto result = std::from_chars(first, last, value);

    if (result.ec != std::errc{} || result.ptr != last) {
        return std::nullopt;
    }

    return value;
}std::optional은 값이 있을 수도 있고 없을 수도 있음을 표현한다. 숫자 변환이 성공하면 변환된 값을 담아 반환하고, 실패하면 std::nullopt를 반환한다. 앞에서 배운 std::optional이 실제 프로그램에서 어떻게 쓰이는지 보여 주는 좋은 예다.
std::stoi, std::stod를 사용해도 된다. 다만 이 함수들은 실패할 때 예외를 던진다. 반면 std::from_chars는 예외를 사용하지 않고 결과 코드로 성공 여부를 알려 준다. 대량의 데이터를 처리할 때는 이런 방식이 더 예측 가능하고 빠른 경우가 많다.
필드 목록을 레코드로 변환하기
이제 CSV 한 줄에서 얻은 필드 목록을 SaleRecord로 바꾸자.
#include <optional>
#include <string>
#include <unordered_map>
#include <vector>

std::optional<SaleRecord> parseSaleRecord(
    const std::vector<std::string>& fields,
    const std::unordered_map<std::string, std::size_t>& index
) {
    auto get = [&](const std::string& name) -> const std::string* {
        auto it = index.find(name);

        if (it == index.end() || it->second >= fields.size()) {
            return nullptr;
        }

        return &fields[it->second];
    };

    const std::string* date = get("date");
    const std::string* region = get("region");
    const std::string* product = get("product");
    const std::string* quantityText = get("quantity");
    const std::string* unitPriceText = get("unit_price");

    if (!date || !region || !product || !quantityText || !unitPriceText) {
        return std::nullopt;
    }

    auto quantity = parseInt(*quantityText);
    auto unitPrice = parseDouble(*unitPriceText);

    if (!quantity || !unitPrice) {
        return std::nullopt;
    }

    if (*quantity < 0 || *unitPrice < 0.0) {
        return std::nullopt;
    }

    SaleRecord record;
    record.date = *date;
    record.region = *region;
    record.product = *product;
    record.quantity = *quantity;
    record.unitPrice = *unitPrice;

    return record;
}
이 함수는 실패할 수 있다. 열이 부족할 수도 있고, 수량 칸에 abc 같은 값이 들어 있을 수도 있다. 그래서 반환 타입을 std::optional<SaleRecord>로 했다. 호출하는 쪽은 결과가 있는지 확인한 뒤에만 std::vector에 추가하면 된다.
여기서 눈여겨볼 부분은 입력 검증이 한곳에 모여 있다는 것이다. 데이터 처리 프로그램에서 가장 지저분해지기 쉬운 부분이 입력 검증이다. 아무 곳에서나 숫자 변환을 하고, 아무 곳에서나 빈 문자열을 검사하면 나중에 어떤 데이터가 유효한지 알기 어려워진다. 행을 레코드로 바꾸는 단계에서 검증 기준을 정하면 이후 단계는 깨끗한 데이터만 다룰 수 있다.
CSV 파일 전체 읽기
이제 파일을 열고 전체 레코드를 읽는 함수를 만들자.
#include <fstream>
#include <iostream>
#include <stdexcept>
#include <string>
#include <utility>
#include <vector>

std::vector<SaleRecord> loadSales(const std::string& path) {
    std::ifstream file(path);

    if (!file) {
        throw std::runtime_error("cannot open input file: " + path);
    }

    std::string line;

    if (!std::getline(file, line)) {
        return {};
    }

    auto headers = splitCsvLine(line);
    auto index = makeHeaderIndex(headers);
    validateHeaders(index);

    std::vector<SaleRecord> records;
    records.reserve(1024);

    int lineNumber = 1;

    while (std::getline(file, line)) {
        ++lineNumber;

        if (trim(line).empty()) {
            continue;
        }

        auto fields = splitCsvLine(line);
        auto record = parseSaleRecord(fields, index);

        if (record) {
            records.push_back(std::move(*record));
        } else {
            std::cerr << "skip invalid line " << lineNumber << 'n';
        }
    }

    return records;
}std::ifstream은 입력 파일 스트림이다. 파일 열기에 실패하면 예외를 던진다. 첫 줄은 헤더로 처리하고, 나머지 줄은 반복해서 읽는다.
records.reserve(1024)도 눈여겨보자. std::vector는 원소가 늘어날 때 내부 배열을 다시 할당할 수 있다. reserve()는 미리 어느 정도 공간을 확보해 재할당 횟수를 줄이는 함수다. 정확한 데이터 크기를 모를 때도 대략적인 초기값을 잡아 두면 도움이 된다.
records.push_back(std::move(*record))에서는 std::move를 사용했다. record 안에는 std::string 멤버가 있으므로 복사보다 이동이 유리할 수 있다. 작은 예제에서는 차이가 거의 없지만, 많은 문자열을 다룰 때는 이런 습관이 성능에 영향을 준다.
map으로 지역과 상품별 집계하기
이제 레코드 목록을 그룹별로 집계해 보자. 그룹 기준은 지역과 상품이다. 즉 Seoul + Keyboard, Busan + Mouse 같은 조합별로 집계를 만든다.
그룹 키를 구조체로 표현하자.
#include <string>
#include <tuple>

struct GroupKey {
    std::string region;
    std::string product;

    bool operator<(const GroupKey& other) const {
        return std::tie(region, product) <
               std::tie(other.region, other.product);
    }
};std::map은 키를 정렬된 상태로 보관한다. 그래서 키 타입에는 비교 기준이 필요하다. 여기서는 std::tie를 사용해 먼저 region을 비교하고, 같으면 product를 비교하게 만들었다.
이제 집계 함수는 아주 짧아진다.
#include <map>
#include <vector>

std::map<GroupKey, Summary>
aggregateByRegionAndProduct(const std::vector<SaleRecord>& records) {
    std::map<GroupKey, Summary> result;

    for (const auto& record : records) {
        GroupKey key{record.region, record.product};
        result[key].add(record);
    }

    return result;
}result[key]는 해당 키가 이미 있으면 기존 값을 반환하고, 없으면 새 Summary를 기본 생성해서 넣은 뒤 반환한다. 그래서 result[key].add(record) 한 줄로 새 그룹 생성과 기존 그룹 갱신을 모두 처리할 수 있다.
이 패턴은 C++ 데이터 처리에서 매우 자주 등장한다.
groups[key].add(record);처음에는 조금 낯설 수 있지만, 익숙해지면 집계 코드가 놀랄 만큼 간단해진다. 단어 빈도수 세기, 사용자별 접속 횟수 계산, 상품별 매출 합산, 날짜별 주문 수 집계가 모두 같은 모양이다.
unordered_map으로 더 빠른 검색 감각 익히기
std::map은 키가 정렬된 상태로 유지된다는 장점이 있다. 하지만 많은 데이터를 다룰 때는 평균적으로 더 빠른 검색을 제공하는 std::unordered_map이 더 적합할 수 있다.
상품별 집계만 따로 만든다면 키가 문자열 하나이므로 std::unordered_map을 간단히 사용할 수 있다.
#include <string>
#include <unordered_map>
#include <vector>

std::unordered_map<std::string, Summary>
aggregateByProduct(const std::vector<SaleRecord>& records) {
    std::unordered_map<std::string, Summary> result;
    result.reserve(records.size());

    for (const auto& record : records) {
        result[record.product].add(record);
    }

    return result;
}
여기서도 result[record.product].add(record) 패턴이 그대로 등장한다. std::unordered_map은 내부적으로 해시를 사용한다. 해시는 키를 숫자처럼 바꿔 빠르게 위치를 찾는 방식이라고 생각하면 된다.
다만 std::unordered_map은 정렬 순서를 보장하지 않는다. 결과를 이름순으로 안정적으로 출력해야 한다면 std::map이 편하다. 반대로 순서가 중요하지 않고 검색과 삽입이 많다면 std::unordered_map이 유리할 수 있다.
정리하면 선택 기준은 단순하다. 키 순서가 필요하면 map, 빠른 평균 검색이 더 중요하면 unordered_map을 먼저 생각하자.
알고리즘으로 필터링하고 정렬하기
데이터를 다룰 때 for문만으로 모든 것을 처리할 수도 있다. 하지만 C++ 표준 알고리즘을 사용하면 의도가 더 분명해진다. 이번에는 std::remove_if, std::transform, std::sort를 사용한다.
먼저 매출이 0인 레코드를 제거해 보자. 수량이 0이거나 단가가 0이면 분석에서 제외하고 싶을 수 있다.
#include <algorithm>
#include <vector>

void removeZeroRevenueRecords(std::vector<SaleRecord>& records) {
    auto newEnd = std::remove_if(
        records.begin(),
        records.end(),
        [](const SaleRecord& record) {
            return record.revenue() == 0.0;
        }
    );

    records.erase(newEnd, records.end());
}std::remove_if는 실제로 컨테이너 크기를 줄이지 않는다. 조건에 맞지 않는 원소들을 앞쪽으로 모으고, 새로운 끝 위치를 반환한다. 그래서 erase()와 함께 써야 한다. 이 패턴을 흔히 erase-remove idiom이라고 부른다.
이번에는 집계 결과를 출력용 행으로 바꾸자.
#include <iterator>
#include <map>
#include <string>
#include <vector>

struct SummaryRow {
    std::string region;
    std::string product;
    int count = 0;
    int quantity = 0;
    double revenue = 0.0;
    double averageRevenue = 0.0;
};

std::vector<SummaryRow>
toSummaryRows(const std::map<GroupKey, Summary>& groups) {
    std::vector<SummaryRow> rows;
    rows.reserve(groups.size());

    std::transform(
        groups.begin(),
        groups.end(),
        std::back_inserter(rows),
        [](const auto& item) {
            const GroupKey& key = item.first;
            const Summary& summary = item.second;

            return SummaryRow{
                key.region,
                key.product,
                summary.count,
                summary.quantity,
                summary.revenue,
                summary.averageRevenue()
            };
        }
    );

    return rows;
}std::transform은 어떤 범위의 값을 다른 형태로 바꿀 때 사용한다. 여기서는 std::map<GroupKey, Summary>의 원소를 SummaryRow로 바꾸어 std::vector에 넣는다.
왜 굳이 std::vector<SummaryRow>로 옮길까? 정렬하기 위해서다. std::map은 키 기준으로 정렬되어 있다. 하지만 우리는 매출이 큰 순서로 출력하고 싶다. std::map 자체의 순서를 매출 기준으로 바꾸기는 어렵다. 대신 출력용 벡터로 옮긴 다음 std::sort를 적용하면 된다.
#include <algorithm>
#include <vector>

void sortByRevenueDescending(std::vector<SummaryRow>& rows) {
    std::sort(
        rows.begin(),
        rows.end(),
        [](const SummaryRow& a, const SummaryRow& b) {
            return a.revenue > b.revenue;
        }
    );
}
람다의 의미도 이제 자연스럽게 읽을 수 있다. a가 b보다 앞에 오려면 a.revenue가 더 커야 한다. 그래서 매출 내림차순 정렬이 된다.
결과를 CSV 파일로 쓰기
입력만큼 중요한 것이 출력이다. 분석 결과가 화면에만 나오면 다시 사용하기 어렵다. CSV 파일로 저장하면 스프레드시트에서 열 수도 있고, 다른 프로그램의 입력으로 넘길 수도 있다.
CSV로 쓸 때도 쉼표와 큰따옴표를 조심해야 한다. 필드 안에 쉼표, 큰따옴표, 줄바꿈이 있으면 큰따옴표로 감싸고, 내부 큰따옴표는 두 번 써야 한다.
#include <string>

std::string escapeCsv(const std::string& value) {
    if (value.find_first_of(",\"nr") == std::string::npos) {
        return value;
    }

    std::string result;
    result.push_back('"');

    for (char ch : value) {
        if (ch == '"') {
            result += "\"\"";
        } else {
            result.push_back(ch);
        }
    }

    result.push_back('"');
    return result;
}
이제 출력 함수를 작성하자.
#include <fstream>
#include <iomanip>
#include <stdexcept>
#include <string>
#include <vector>

void writeSummaryCsv(
    const std::string& path,
    const std::vector<SummaryRow>& rows
) {
    std::ofstream out(path);

    if (!out) {
        throw std::runtime_error("cannot open output file: " + path);
    }

    out << "region,product,count,quantity,revenue,average_revenuen";
    out << std::fixed << std::setprecision(2);

    for (const auto& row : rows) {
        out << escapeCsv(row.region) << ','
            << escapeCsv(row.product) << ','
            << row.count << ','
            << row.quantity << ','
            << row.revenue << ','
            << row.averageRevenue << 'n';
    }
}std::fixed와 std::setprecision(2)를 사용하면 실수를 소수점 둘째 자리까지 출력한다. 돈을 다룰 때는 사실 double보다 정수 단위, 예를 들어 원 단위 정수나 센트 단위 정수로 처리하는 편이 더 안전하다. 하지만 이번 예제에서는 흐름을 단순하게 유지하기 위해 double을 사용한다.
또 하나 눈여겨볼 점은 std::endl 대신 n을 사용했다는 것이다. std::endl은 줄바꿈뿐 아니라 출력 버퍼를 강제로 비운다. 자주 호출하면 느려질 수 있다. 단순히 줄을 바꾸고 싶을 때는 n이면 충분하다.
전체 프로그램 조립하기
이제 조각들을 하나의 파일로 합쳐 보자. 파일 이름은 mini_sales.cpp라고 하겠다.
#include <algorithm>
#include <charconv>
#include <cctype>
#include <fstream>
#include <iomanip>
#include <iostream>
#include <iterator>
#include <map>
#include <optional>
#include <stdexcept>
#include <string>
#include <system_error>
#include <tuple>
#include <unordered_map>
#include <utility>
#include <vector>

struct SaleRecord {
    std::string date;
    std::string region;
    std::string product;
    int quantity = 0;
    double unitPrice = 0.0;

    double revenue() const {
        return quantity * unitPrice;
    }
};

struct Summary {
    int count = 0;
    int quantity = 0;
    double revenue = 0.0;

    void add(const SaleRecord& record) {
        ++count;
        quantity += record.quantity;
        revenue += record.revenue();
    }

    double averageRevenue() const {
        if (count == 0) {
            return 0.0;
        }
        return revenue / count;
    }
};

struct GroupKey {
    std::string region;
    std::string product;

    bool operator<(const GroupKey& other) const {
        return std::tie(region, product) <
               std::tie(other.region, other.product);
    }
};

struct SummaryRow {
    std::string region;
    std::string product;
    int count = 0;
    int quantity = 0;
    double revenue = 0.0;
    double averageRevenue = 0.0;
};

std::string trim(const std::string& text) {
    std::size_t begin = 0;

    while (begin < text.size() &&
           std::isspace(static_cast<unsigned char>(text[begin]))) {
        ++begin;
    }

    std::size_t end = text.size();

    while (end > begin &&
           std::isspace(static_cast<unsigned char>(text[end - 1]))) {
        --end;
    }

    return text.substr(begin, end - begin);
}

std::vector<std::string> splitCsvLine(const std::string& line) {
    std::vector<std::string> fields;
    std::string field;
    bool inQuotes = false;

    for (std::size_t i = 0; i < line.size(); ++i) {
        char ch = line[i];

        if (ch == '"') {
            if (inQuotes && i + 1 < line.size() && line[i + 1] == '"') {
                field.push_back('"');
                ++i;
            } else {
                inQuotes = !inQuotes;
            }
        } else if (ch == ',' && !inQuotes) {
            fields.push_back(trim(field));
            field.clear();
        } else {
            field.push_back(ch);
        }
    }

    fields.push_back(trim(field));
    return fields;
}

std::unordered_map<std::string, std::size_t>
makeHeaderIndex(const std::vector<std::string>& headers) {
    std::unordered_map<std::string, std::size_t> index;

    for (std::size_t i = 0; i < headers.size(); ++i) {
        index[headers[i]] = i;
    }

    return index;
}

void validateHeaders(const std::unordered_map<std::string, std::size_t>& index) {
    const char* required[] = {
        "date",
        "region",
        "product",
        "quantity",
        "unit_price"
    };

    for (const char* name : required) {
        if (index.find(name) == index.end()) {
            throw std::runtime_error(std::string("missing header: ") + name);
        }
    }
}

std::optional<int> parseInt(const std::string& text) {
    int value = 0;
    const char* first = text.data();
    const char* last = text.data() + text.size();

    auto result = std::from_chars(first, last, value);

    if (result.ec != std::errc{} || result.ptr != last) {
        return std::nullopt;
    }

    return value;
}

std::optional<double> parseDouble(const std::string& text) {
    double value = 0.0;
    const char* first = text.data();
    const char* last = text.data() + text.size();

    auto result = std::from_chars(first, last, value);

    if (result.ec != std::errc{} || result.ptr != last) {
        return std::nullopt;
    }

    return value;
}

std::optional<SaleRecord> parseSaleRecord(
    const std::vector<std::string>& fields,
    const std::unordered_map<std::string, std::size_t>& index
) {
    auto get = [&](const std::string& name) -> const std::string* {
        auto it = index.find(name);

        if (it == index.end() || it->second >= fields.size()) {
            return nullptr;
        }

        return &fields[it->second];
    };

    const std::string* date = get("date");
    const std::string* region = get("region");
    const std::string* product = get("product");
    const std::string* quantityText = get("quantity");
    const std::string* unitPriceText = get("unit_price");

    if (!date || !region || !product || !quantityText || !unitPriceText) {
        return std::nullopt;
    }

    auto quantity = parseInt(*quantityText);
    auto unitPrice = parseDouble(*unitPriceText);

    if (!quantity || !unitPrice) {
        return std::nullopt;
    }

    if (*quantity < 0 || *unitPrice < 0.0) {
        return std::nullopt;
    }

    SaleRecord record;
    record.date = *date;
    record.region = *region;
    record.product = *product;
    record.quantity = *quantity;
    record.unitPrice = *unitPrice;

    return record;
}

std::vector<SaleRecord> loadSales(const std::string& path) {
    std::ifstream file(path);

    if (!file) {
        throw std::runtime_error("cannot open input file: " + path);
    }

    std::string line;

    if (!std::getline(file, line)) {
        return {};
    }

    auto headers = splitCsvLine(line);
    auto index = makeHeaderIndex(headers);
    validateHeaders(index);

    std::vector<SaleRecord> records;
    records.reserve(1024);

    int lineNumber = 1;

    while (std::getline(file, line)) {
        ++lineNumber;

        if (trim(line).empty()) {
            continue;
        }

        auto fields = splitCsvLine(line);
        auto record = parseSaleRecord(fields, index);

        if (record) {
            records.push_back(std::move(*record));
        } else {
            std::cerr << "skip invalid line " << lineNumber << 'n';
        }
    }

    return records;
}

void removeZeroRevenueRecords(std::vector<SaleRecord>& records) {
    auto newEnd = std::remove_if(
        records.begin(),
        records.end(),
        [](const SaleRecord& record) {
            return record.revenue() == 0.0;
        }
    );

    records.erase(newEnd, records.end());
}

std::map<GroupKey, Summary>
aggregateByRegionAndProduct(const std::vector<SaleRecord>& records) {
    std::map<GroupKey, Summary> result;

    for (const auto& record : records) {
        GroupKey key{record.region, record.product};
        result[key].add(record);
    }

    return result;
}

std::unordered_map<std::string, Summary>
aggregateByProduct(const std::vector<SaleRecord>& records) {
    std::unordered_map<std::string, Summary> result;
    result.reserve(records.size());

    for (const auto& record : records) {
        result[record.product].add(record);
    }

    return result;
}

std::vector<SummaryRow>
toSummaryRows(const std::map<GroupKey, Summary>& groups) {
    std::vector<SummaryRow> rows;
    rows.reserve(groups.size());

    std::transform(
        groups.begin(),
        groups.end(),
        std::back_inserter(rows),
        [](const auto& item) {
            const GroupKey& key = item.first;
            const Summary& summary = item.second;

            return SummaryRow{
                key.region,
                key.product,
                summary.count,
                summary.quantity,
                summary.revenue,
                summary.averageRevenue()
            };
        }
    );

    return rows;
}

void sortByRevenueDescending(std::vector<SummaryRow>& rows) {
    std::sort(
        rows.begin(),
        rows.end(),
        [](const SummaryRow& a, const SummaryRow& b) {
            return a.revenue > b.revenue;
        }
    );
}

std::string escapeCsv(const std::string& value) {
    if (value.find_first_of(",\"nr") == std::string::npos) {
        return value;
    }

    std::string result;
    result.push_back('"');

    for (char ch : value) {
        if (ch == '"') {
            result += "\"\"";
        } else {
            result.push_back(ch);
        }
    }

    result.push_back('"');
    return result;
}

void writeSummaryCsv(
    const std::string& path,
    const std::vector<SummaryRow>& rows
) {
    std::ofstream out(path);

    if (!out) {
        throw std::runtime_error("cannot open output file: " + path);
    }

    out << "region,product,count,quantity,revenue,average_revenuen";
    out << std::fixed << std::setprecision(2);

    for (const auto& row : rows) {
        out << escapeCsv(row.region) << ','
            << escapeCsv(row.product) << ','
            << row.count << ','
            << row.quantity << ','
            << row.revenue << ','
            << row.averageRevenue << 'n';
    }
}

int main(int argc, char* argv[]) {
    if (argc < 3) {
        std::cout << "usage: " << argv[0]
                  << " <input.csv> <output.csv>n";
        return 1;
    }

    try {
        std::vector<SaleRecord> records = loadSales(argv[1]);
        removeZeroRevenueRecords(records);

        auto productGroups = aggregateByProduct(records);
        auto regionProductGroups = aggregateByRegionAndProduct(records);

        std::vector<SummaryRow> rows = toSummaryRows(regionProductGroups);
        sortByRevenueDescending(rows);

        writeSummaryCsv(argv[2], rows);

        std::cout << "records: " << records.size() << 'n';
        std::cout << "product groups: " << productGroups.size() << 'n';
        std::cout << "summary rows: " << rows.size() << 'n';
        std::cout << "written: " << argv[2] << 'n';
    } catch (const std::exception& e) {
        std::cerr << "error: " << e.what() << 'n';
        return 1;
    }

    return 0;
}
코드가 꽤 길어 보이지만, 기능별로 나누어 보면 복잡하지 않다. CSV 분리, 숫자 변환, 레코드 파싱, 파일 읽기, 집계, 정렬, 파일 쓰기가 각각 함수 하나로 분리되어 있다. 실전 코드에서는 이런 분리가 매우 중요하다. 한 함수가 모든 일을 하면 처음에는 빨라 보이지만, 수정할 때마다 점점 더 위험해진다.
컴파일하고 실행하기
터미널에서 다음처럼 컴파일할 수 있다.
g++ -std=c++20 -O2 mini_sales.cpp -o mini_salesClang을 사용한다면 다음처럼 컴파일할 수 있다.
clang++ -std=c++20 -O2 mini_sales.cpp -o mini_sales실행은 입력 파일과 출력 파일을 인자로 넘긴다.
./mini_sales sales.csv summary.csvWindows PowerShell에서는 실행 파일 이름이 다를 수 있다.
.mini_sales.exe sales.csv summary.csv정상적으로 실행되면 대략 다음과 같은 메시지가 나온다.
records: 6
product groups: 3
summary rows: 6
written: summary.csv
그리고 summary.csv 파일이 생성된다. 이 파일을 스프레드시트에서 열어 보면 지역과 상품별 매출 집계가 정렬되어 있는 것을 확인할 수 있다.
성능을 의식한 작은 선택들
데이터가 100줄일 때는 어떤 방식으로 작성해도 대부분 빠르다. 하지만 100만 줄, 1천만 줄이 되면 이야기가 달라진다. C++의 장점은 이런 상황에서 세부 선택을 조절할 수 있다는 데 있다.
이번 예제에 이미 들어간 성능 관련 선택들을 다시 살펴보자.
std::vector::reserve()로 재할당 횟수를 줄였다.for (const auto& record : records)처럼 불필요한 복사를 피했다.std::from_chars로 예외 없는 숫자 변환을 사용했다.std::move(*record)로 문자열이 들어 있는 레코드를 이동했다.std::unordered_map::reserve()로 해시 테이블의 재배치를 줄였다.std::endl대신n을 사용해 불필요한 flush를 피했다.
이런 선택 하나하나는 작아 보인다. 하지만 데이터가 커질수록 작은 차이가 쌓인다. 특히 문자열 처리는 비용이 큰 편이다. 문자열을 자주 복사하거나, 같은 값을 반복해서 파싱하거나, 필요 없는 임시 객체를 많이 만들면 프로그램은 금방 느려진다.
물론 성능 개선에는 순서가 있다. 처음부터 모든 것을 최적화하려고 하면 코드가 지나치게 복잡해진다. 먼저 올바르게 동작하는 구조를 만들고, 그다음 실제 데이터로 측정하면서 병목을 찾아 고치는 것이 좋다. C++은 빠른 코드를 쓸 수 있는 언어이지만, 빠를 것이라고 상상한 코드가 항상 빠른 것은 아니다.
큰 파일을 다룰 때는 저장하지 않고 집계할 수도 있다
이번 장에서는 std::vector<SaleRecord>에 모든 레코드를 저장했다. 이 방식은 데이터를 여러 번 살펴보거나, 정렬하거나, 추가 분석을 할 때 유용하다. 하지만 목표가 단순 집계뿐이라면 모든 행을 메모리에 저장할 필요가 없다.
파일을 읽으면서 바로 집계할 수도 있다.
std::map<GroupKey, Summary> aggregateSalesFromFile(const std::string& path) {
    std::ifstream file(path);

    if (!file) {
        throw std::runtime_error("cannot open input file: " + path);
    }

    std::string line;

    if (!std::getline(file, line)) {
        return {};
    }

    auto headers = splitCsvLine(line);
    auto index = makeHeaderIndex(headers);
    validateHeaders(index);

    std::map<GroupKey, Summary> groups;

    while (std::getline(file, line)) {
        if (trim(line).empty()) {
            continue;
        }

        auto fields = splitCsvLine(line);
        auto record = parseSaleRecord(fields, index);

        if (!record || record->revenue() == 0.0) {
            continue;
        }

        GroupKey key{record->region, record->product};
        groups[key].add(*record);
    }

    return groups;
}
이 방식은 메모리를 훨씬 적게 사용한다. 입력 파일이 아무리 커도 메모리에는 집계 결과만 남는다. 대신 원본 레코드를 다시 정렬하거나, 여러 기준으로 반복 분석하기는 어렵다.
따라서 선택은 목적에 따라 달라진다. 데이터를 여러 방식으로 분석해야 한다면 vector에 저장하는 편이 좋다. 한 번 읽고 하나의 결과만 만들면 된다면 읽으면서 바로 집계하는 방식이 더 효율적이다.
문자열 처리 비용 줄이기
CSV 처리에서 가장 비싼 작업 중 하나는 문자열이다. 한 줄을 읽고, 필드로 나누고, 각 필드를 새 std::string으로 만들고, 다시 구조체에 복사한다. 데이터가 작으면 괜찮지만, 매우 큰 파일에서는 부담이 된다.
더 고급 방식으로는 std::string_view를 사용할 수 있다. std::string_view는 문자열을 소유하지 않고, 기존 문자열의 일부를 가리키는 가벼운 객체다. 복사를 줄일 수 있지만 주의할 점도 있다. 원본 문자열이 사라지면 string_view도 더 이상 안전하지 않다.
예를 들어 파일을 한 줄씩 읽을 때 line 변수는 반복마다 내용이 바뀐다. 그 line 내부를 가리키는 string_view를 vector에 저장하면 다음 줄을 읽는 순간 위험해질 수 있다. 그래서 string_view는 수명 관리가 확실할 때만 사용해야 한다.
입문 단계에서는 먼저 std::string으로 안전하게 구현하자. 이후 실제 병목이 문자열 복사로 확인되면 그때 string_view, 문자열 인터닝, 메모리 풀 같은 기법을 검토하면 된다. 빠른 코드는 좋지만, 틀린 빠른 코드는 쓸모가 없다.
map, vector, algorithm이 만나는 지점
이번 예제는 지금까지 배운 표준 라이브러리의 조합을 보여 준다. std::vector는 입력 레코드를 순서대로 담는 데 사용했다. std::map은 지역과 상품 조합별 집계에 사용했다. std::unordered_map은 상품명으로 빠르게 그룹을 찾는 예를 보여 주었다. std::sort, std::transform, std::remove_if는 데이터를 필터링하고 변환하고 정렬하는 데 사용했다.
이 조합을 익히면 C++로 할 수 있는 일이 갑자기 넓어진다. 직접 연결 리스트를 만들거나 정렬 알고리즘을 구현하지 않아도 된다. 표준 라이브러리가 제공하는 검증된 도구를 가져와 문제에 맞게 조립하면 된다.
여기서 중요한 것은 컨테이너 하나를 외우는 것이 아니다. 어떤 데이터가 들어오고, 어떤 형태로 바꾸고, 어떤 기준으로 찾고 정렬할지를 생각하는 힘이 중요하다. C++의 STL은 그 생각을 코드로 옮기는 강력한 도구다.
조금 더 실전처럼 확장하기
이 프로그램은 작은 출발점이다. 하지만 몇 가지 기능을 더하면 실제로 쓸 만한 도구가 된다.
명령행 인자로 최소 매출, 특정 지역, 특정 상품 필터를 받을 수 있다.
날짜별 집계, 지역별 집계, 상품별 집계를 선택해서 출력할 수 있다.
잘못된 행을 별도의 오류 파일에 저장해 나중에 확인할 수 있다.
출력 결과를 매출순뿐 아니라 이름순, 수량순으로 정렬할 수 있다.
테스트용 CSV 파일을 만들어 파서와 집계 함수의 동작을 자동으로 확인할 수 있다.
예를 들어 --region Seoul 같은 옵션을 받으면 서울 데이터만 분석할 수 있다. --min-revenue 100000을 받으면 매출이 일정 금액 이상인 거래만 남길 수 있다. 이런 기능을 추가하다 보면 자연스럽게 프로젝트 구조, 예외 처리 정책, 함수 분리, 테스트 코드가 필요해진다.
이것이 실전 프로젝트가 커지는 방식이다. 처음부터 거대한 설계를 하는 것이 아니라, 작고 명확한 프로그램을 만든 뒤 요구사항이 생길 때마다 구조를 다듬는다.
이번 장에서 얻은 감각
이번 장에서는 C++로 작은 데이터 처리 도구를 만들었다. 겉으로는 CSV 파일 하나를 읽고 결과 파일 하나를 쓰는 프로그램이지만, 안에는 실전 C++의 중요한 감각이 많이 들어 있다.
CSV 파일을 읽을 때는 헤더, 행, 열을 분리해야 한다. 읽은 문자열은 적절한 타입으로 변환해야 한다. 변환에 실패할 수 있으므로 std::optional 같은 타입으로 실패 가능성을 표현하면 코드가 명확해진다. 레코드는 구조체로 만들고, 여러 레코드는 std::vector에 저장한다. 그룹별 집계에는 std::map과 std::unordered_map을 사용할 수 있다. 결과를 보기 좋게 만들려면 std::transform으로 형태를 바꾸고, std::sort로 정렬하고, std::remove_if로 필요 없는 데이터를 제거한다.
C++은 단순히 빠른 언어가 아니다. 데이터를 어떤 타입으로 표현할지, 누가 소유할지, 언제 복사하고 언제 이동할지, 어떤 컨테이너를 선택할지 계속 생각하게 만드는 언어다. 그 생각이 처음에는 어렵게 느껴지지만, 익숙해지면 복잡한 문제를 단단한 코드로 바꾸는 힘이 된다.
게임을 만들 때도, 서버 로그를 분석할 때도, 금융 거래 기록을 처리할 때도, 센서 데이터를 집계할 때도 기본 흐름은 같다. 읽고, 표현하고, 검증하고, 집계하고, 정렬하고, 저장한다. 이번 장의 미니 도구는 그 흐름을 C++다운 방식으로 경험하는 작은 실험실이다.
이 노트는 보도·비평·교육·연구 목적으로 작성되었습니다. 저작권 문의가 있으시면 에서 알려주세요.